News AI Models
Qwen4-Max Alibaba Debuts as 2.4 Trillion Parameter MoE Model via API
Alibaba launched Qwen4-Max on November 16, 2026, as a 2.4 trillion parameter sparse MoE model accessible exclusively through its cloud platforms.
Alibaba released Qwen4-Max on November 16, 2026, in Hangzhou. The model serves as the first entry in the Qwen4 series and operates solely through hosted APIs on QwenCloud, Token Plan, Qwen Studio, QwenWork, and Qoder.
The release provides no downloadable weights. Smaller open-weight models from the same series are planned for later distribution, though Alibaba supplied no timelines or model sizes.
Qwen4-Max Technical Specifications and Architecture
Qwen4-Max uses a sparse Mixture-of-Experts design with a 2.4 trillion parameter backbone. Only 71 billion parameters activate per token, a 25 percent reduction compared with Qwen3.8-Max at equivalent scale. The system also incorporates roughly 328 billion additional N-gram embedding parameters. New components include Qwen Sparse Attention, Gated Residuals, and DeltaNet elements that improve efficiency during long-context processing.
Input modalities cover text, images, and video, while output remains text only. The context window reaches one million tokens, with practical limits between 983,000 and 991,000 input tokens depending on the active reasoning mode. Independent tests place the model behind certain U.S. systems on select agent and coding benchmarks, while Alibaba reports leading positions on its internal specialized evaluations.
Pricing, Performance, and Market Context
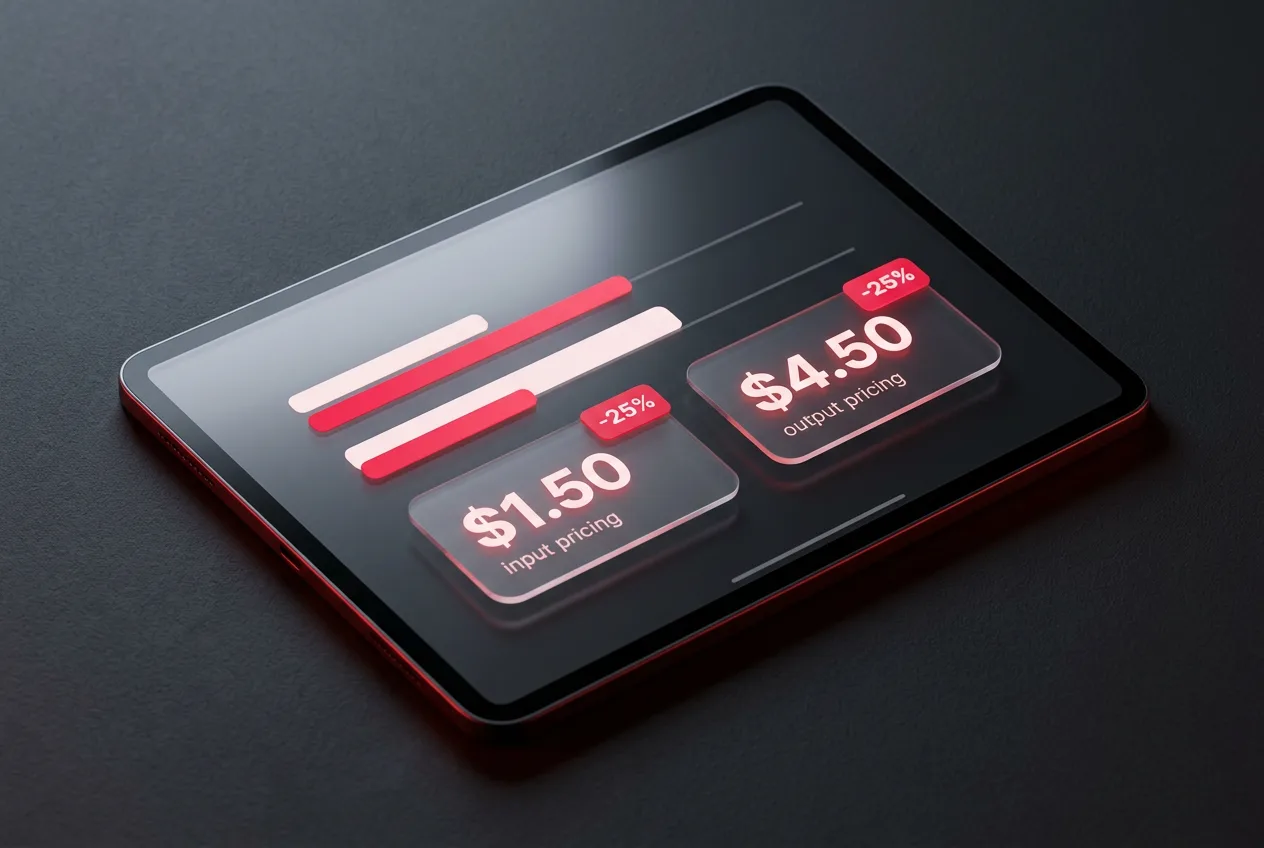
International list pricing stands at $1.50 per million input tokens and $4.50 per million output tokens. Implicit cache hits cost $0.075 per million tokens. These rates sit approximately 25 percent below Qwen3.8-Max, with cached input reduced by about 70 percent. On the proprietary Work360 benchmark covering 721 specialized fields, the model delivers higher overall scores than its predecessor while consuming 35 percent fewer tokens in high-effort mode and cutting average task cost by 60 to 62 percent.
A preview version labeled qwen4-max-preview operated from November 11 through November 25, 2026, under the Token Plan before the production release took effect. The architecture targets production workloads that require extended context and multimodal inputs without local deployment.
Frequently asked questions
Is Qwen4-Max available for local download?
No. The model runs exclusively through Alibaba-hosted APIs on QwenCloud and related platforms. No weights are offered for self-hosting.
What context length does Qwen4-Max support?
The model provides a one-million-token context window. Practical input limits range from 983,000 to 991,000 tokens depending on reasoning mode.
How does Qwen4-Max pricing compare with the previous version?
Input tokens cost $1.50 per million and output tokens $4.50 per million. These figures are about 25 percent lower than Qwen3.8-Max, with cached input reduced by roughly 70 percent.
Will smaller Qwen4 models be released as open weights?
Alibaba indicated that smaller-scale open-weight models from the Qwen4 series will be released later, but no specific dates, sizes, or license details have been provided.
Comments
No comments yet. Be the first!