News AI
MiniMax M3.1 Flash AI Model Released for Agentic and Coding Tasks
Chinese AI startup MiniMax released the M3.1 Flash model on October 19, 2026, claiming major gains in agentic tasks, coding and cybersecurity at lower cost.
Chinese AI startup MiniMax released the MiniMax M3.1 Flash model on October 19, 2026. The new model, available immediately through the company API, targets agentic workflows, coding, computer use and cybersecurity applications.
MiniMax M3.1 Flash Model Architecture and Benchmarks
The model uses a mixture-of-experts design with roughly 428 billion total parameters and 23 billion active parameters. It supports a 1-million-token context window and accepts text, image and video inputs while producing text outputs. Always-on reasoning runs across five tunable effort levels that cannot be disabled, with the default set to maximum.
MiniMax reports online inference nearly three times faster than the prior version, with everyday output exceeding 200 tokens per second and P50 latency around 170 tokens per second. The company also states agentic-task usage costs run about 70 percent lower than the predecessor. Self-reported benchmark scores include 62.2 on Automation-Bench, 73.7 percent on DeepSWE v1.1, 61.7 on OSWorld V2, 29.6 to 30 percent on Agents Last Exam, 76.2 on BankerToolBench and 82 percent on CyberGym.
The model evolved from an earlier anonymous system that processed more than 200 trillion tokens. A preview version had been available since September 27, 2026, through MiniMax Code and subscription plans. MiniMax positions the M3.1 Flash tier as a cost-efficient complement to its higher-intelligence M3 line.
API Pricing and Immediate Availability
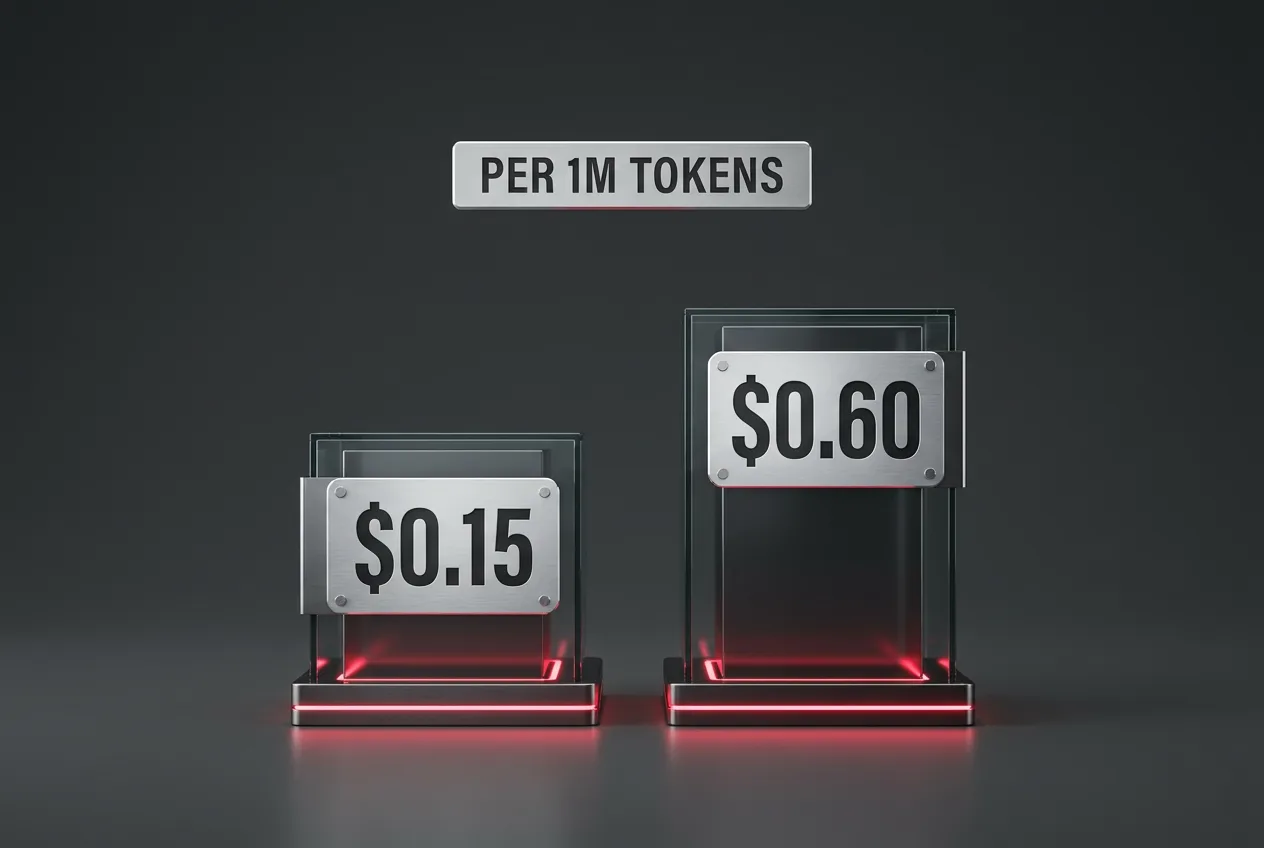
Flat API pricing stands at 0.15 dollars per million input tokens, 0.60 dollars per million output tokens and 0.015 dollars per million cached input tokens, with no length-based tiers. Access opened immediately through the MiniMax API, the M Plan subscription and the MiniMax Code desktop application.
Model weights are scheduled for release later in the month, with one report indicating October 23. The company has also mentioned plans for a future Pro variant that would deliver greater capability while retaining the same architecture family.
Market Context for MiniMax M3.1 Flash
MiniMax, listed as 0100.HK, continues to expand its model lineup after earlier releases in the M3 series. The M3.1 Flash announcement arrives alongside broader industry movement toward specialized models that balance speed and cost for repeated agentic and tool-use workloads.
Third-party evaluations of the new model are expected in the coming weeks. Wider API access expansions and additional benchmark comparisons will provide further data on how the model performs against established alternatives in production environments.
Frequently asked questions
When did MiniMax release the M3.1 Flash model?
MiniMax released the M3.1 Flash model on October 19, 2026. The model became available the same day through the company API and subscription plans.
What input and output pricing applies to the MiniMax M3.1 Flash API?
The API charges 0.15 dollars per million input tokens and 0.60 dollars per million output tokens. Cached input tokens cost 0.015 dollars per million with no length tiers.
What context window does the MiniMax M3.1 Flash model support?
The model supports a 1-million-token context window. It accepts text, image and video inputs while returning text outputs.
When will MiniMax release the M3.1 Flash model weights?
MiniMax plans to release model weights later in October 2026. One report points to October 23 as the scheduled date.
Comments 2